When Small Parquet Files Become a Big Problem (and How I Ended Up Writing a Compactor in PyArrow)

It all began with a fairly normal data pipeline, the kind I've built dozens of times over the years working with event-driven systems on AWS. Events were coming in through Kafka, landing in AWS S3 as Parquet files after going through some lightweight microbatch processing. It looked clean at first glance. Efficient. Predictable. But one day I opened one of the hourly folders and saw the mess I had accidentally created - hundreds of files inside, many of them barely a few kilobytes in size.
The Hidden Cost of Small Parquet Files in S3
Parquet is supposed to be efficient. It's columnar, compressed and designed for analytics workflows. But what no one warns you about is the moment your pipeline turns into a file factory. All of these tiny files, written frequently and automatically, start to accumulate - not just in number, but in overhead.
And that overhead isn't just technical. In Amazon S3 each object has a minimum billable size of 128 KB, which means that even if your file is just a few kilobytes, you're still charged as if it were 128. When you're generating hundreds or thousands of microfiles per hour, those costs begin to compound.
The total storage might seem small, but the object count, listing time and the way tools like Athena handle fragmented input quickly turn into real bottlenecks. The pipeline wasn't broken, but it was clearly becoming bloated and inefficient - and I knew I had to do something about it.
Why Not Spark, Glue, Dask or DuckDB?
Before writing any code I did what any decent engineer does - I looked around to see if someone had already solved this better than I could. Spark was the first thing that came to mind. It handles Parquet well, it's fast and it's distributed, but it felt like a very heavyweight solution to what was essentially a file housekeeping problem.
AWS Glue looked tempting too: it's serverless and works well with Parquet, but it takes a while to spin up and the costs can add up quickly if you're running frequent jobs or dealing with lots of small files.
Dask crossed my radar, but I've learned to be cautious with it when dealing with S3. DuckDB was the most fun to consider. I genuinely enjoy working with it locally, but since I was running this pipeline inside a Kubernetes pod with limited memory, I wasn't convinced it could handle a few hundred files at once without eventually tripping over itself.
PyArrow Was Already There - So I Used It
In the end I kept circling back to PyArrow. I was already using it for smaller pieces of the pipeline and it just fit. No orchestration, no YAML, no spark-submit, no platform overhead. I wasn't trying to rebuild the world. I wanted to reduce the clutter.
To test things out I grabbed the January 2025 Yellow Taxi trip dataset from the NYC open data portal. I took the full Parquet file and split it into smaller pieces - 696 files, to be exact, each with 5,000 rows and roughly 100 KB in size. That's roughly the shape and size you might get from a streaming pipeline that flushes frequently or microbatches on small intervals. It felt like a realistic simulation of a production mess.
Here’s the code I used to break it up:
import pyarrow.parquet as pq
import pyarrow.dataset as ds
import pyarrow as pa
import os

source_path = "yellow_tripdata_2025-01.parquet"
output_base = "demo_data"

dataset = ds.dataset(source_path, format="parquet")
batches = dataset.to_batches(batch_size=5000)
Splitting a full Parquet file into smaller batches of 5,000 rows each
A quick aside: pyarrow.dataset lets you treat a collection of files like one logical table, which makes it really easy to load, transform, or compact data across many files without having to read everything into memory at once. If you haven’t used it before, it’s worth checking out. Here’s the documentation.
Once I had the folder full of microfiles, I wrote a short script using pyarrow.dataset to read all of them, merge them into a single dataset, and write them back out compacted. You can play with parameters like min_rows_per_group, max_rows_per_group, and max_rows_per_file to tune the output size - and it’s amazing how much control you get from just a few lines of code. Here's what the compaction part looked like:
from pyarrow import fs
import pyarrow.dataset as ds

def list_parquet_files(local_fs, path):
    file_infos = local_fs.get_file_info(fs.FileSelector(path, recursive=True))
    parquet_files = [
        info.path
        for info in file_infos
        if info.type == fs.FileType.File and info.path.endswith(".parquet")
    ]
    return parquet_files

local_fs = fs.LocalFileSystem()

files = list_parquet_files(local_fs, "demo_data")
print(f"Found {len(files)} input files")

dataset = ds.dataset(
        files,
        format="parquet",
        filesystem=local_fs,
    )

min_rows_per_group = 500
max_rows_per_file = 1000000
max_rows_per_group = 10000

ds.write_dataset(
    dataset,
    "output_demo_data",
    format="parquet",
    basename_template=f"compacted_{{i}}.parquet",
    min_rows_per_group=min_rows_per_group,
    max_rows_per_file=max_rows_per_file,
    max_rows_per_group=max_rows_per_group,
    existing_data_behavior="overwrite_or_ignore",
    use_threads=True,
    filesystem=fs.LocalFileSystem(),
    file_options=ds.ParquetFileFormat().make_write_options(compression="gzip"),
)
Reading all small files as one dataset and writing them back compacted with tuned row groups
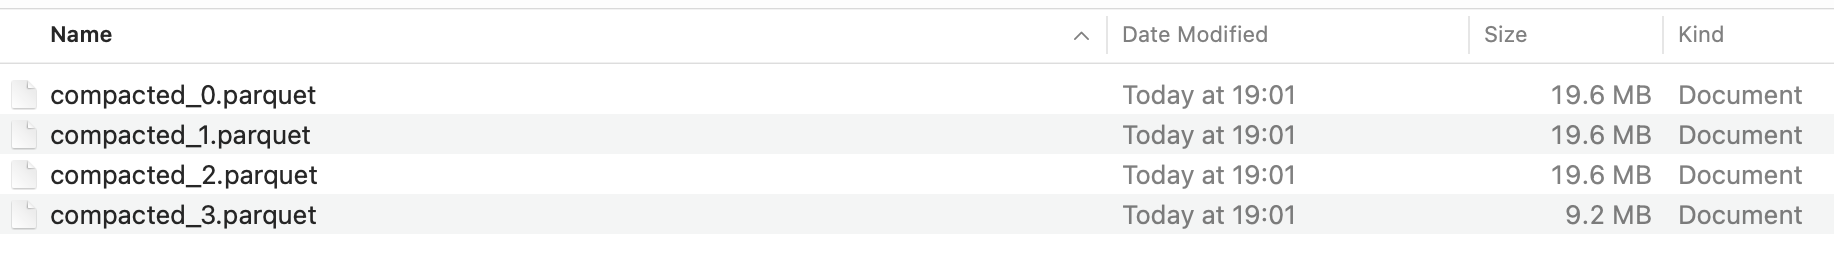
And just like that, 696 scattered files became 4 clean ones - three at 19.6 MB and one at 9.2 MB. Instead of hundreds of undersized objects dragging down every query and inflating my S3 bill, I had four well-structured files that were fast to scan and cheap to store.
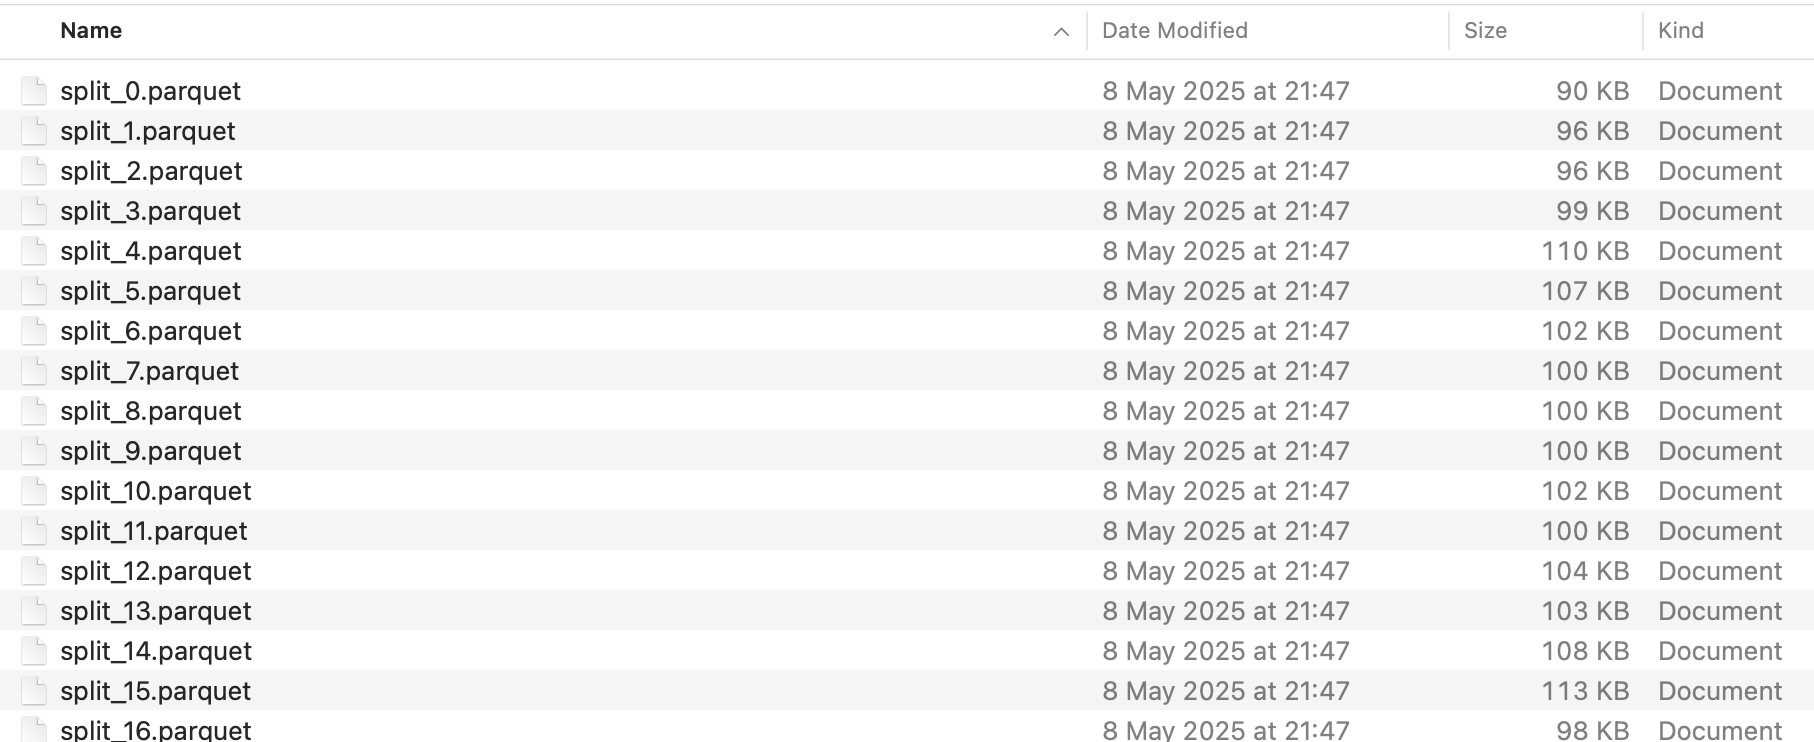
It worked perfectly during testing, when I ran it on a small folder with just a handful of files. But in real data some hours are busier than others. Depending on traffic a single hourly folder might end up with thousands of files, and that’s where things started to fall apart. PyArrow’s dataset method tries to read them all at once, and while it gives you a lot of control, it also assumes you know what kind of load you're about to put on your system. I didn’t think much of it until I ran the compactor in a Kubernetes pod and hit an out-of-memory error. Turns out that even small Parquet files can add up fast, especially once you account for all the metadata and row groups that get loaded into memory behind the scenes.
Batching to Avoid Out-of-Memory Errors
So I rewrote the whole thing with batching in mind. Instead of loading every file at once I grouped them into chunks of 100, read each batch, compacted it into a new file, cleaned up memory and moved on. It was simple, but effective. Here’s what the final version looked like:
import pyarrow.dataset as ds
from pyarrow import fs
import os

def list_parquet_files(local_fs, path):
    file_infos = local_fs.get_file_info(fs.FileSelector(path, recursive=True))
    return [
        info.path
        for info in file_infos
        if info.type == fs.FileType.File and info.path.endswith(".parquet")
    ]


input_path = 'demo_data'
output_path = 'output_demo_data_batched'
files_per_batch = 100
min_rows_per_group = 500
max_rows_per_file = 1000000
max_rows_per_group = 10000

local_fs = fs.LocalFileSystem()

all_files = list_parquet_files(local_fs, input_path)
print(f"Found {len(all_files)} input files")

os.makedirs(output_path, exist_ok=True)

for batch_idx in range(0, len(all_files), files_per_batch):
    batch_files = all_files[batch_idx: batch_idx + files_per_batch]
    print(f"Processing files {batch_idx} to {batch_idx + len(batch_files)}")

    dataset = ds.dataset(batch_files, format="parquet", filesystem=local_fs)

    ds.write_dataset(
        dataset,
        output_path,
        format="parquet",
        basename_template=f"compacted_batch_{batch_idx // files_per_batch}_{{i}}.parquet",
        min_rows_per_group=min_rows_per_group,
        max_rows_per_file=max_rows_per_file,
        max_rows_per_group=max_rows_per_group,
        existing_data_behavior="overwrite_or_ignore",
        use_threads=True,
        filesystem=local_fs,
        file_options=ds.ParquetFileFormat().make_write_options(compression="gzip"),
    )

    del dataset
Final version with batching, memory cleanup and GZIP compression
This version is just as fast for small volumes but doesn’t choke when you throw hundreds of files at it. You can tune the batch size depending on your available memory, and the output files will still be cleanly structured and compressed.
Want to Run This on S3?
If you're testing locally, all you need to switch to S3 is one line. Replace fs.LocalFileSystem() with fs.S3FileSystem(region="us-east-1"), and it will just work. If you’ve configured AWS credentials in your environment, PyArrow will find them. If not, you can pass them directly like this:
s3 = fs.S3FileSystem(
    access_key="YOUR_ACCESS_KEY",
    secret_key="YOUR_SECRET_KEY",
    region="us-east-1"
)
And That Was It
With those changes in place, the compactor stopped being a quick experiment and started acting like a real tool. It processed hundreds of fragmented objects, merged them in manageable batches and wrote them out with GZIP compression and reasonable row group sizes. The output was tidy, fast to scan and cheap to store.
And memory? Solid. I monitored usage during the first few runs, but after that it just ran quietly in the background, doing its job without drawing attention, which is honestly the best thing you can say about any data pipeline component. I’ve had it running in production for a while now and I haven’t needed to touch it since.
If You’re Drowning in Tiny Files Too...
You probably don’t need Spark. You probably don’t need Glue. What you need is a little script that knows how to behave, keeps its memory to itself and quietly cleans up after your streaming pipeline. PyArrow might not be flashy, but for jobs like this, it’s exactly what you want - just enough control to get it done without dragging in a whole data platform.
If you're dealing with the same kind of file sprawl, give it a try. Clone the repo, point it at your own S3 folder and see how much you can tidy up. I'd love to hear how it goes - drop me a message or open an issue if you run into anything.
📂 Code is available in the repo
📚 Learn more about pyarrow.dataset